- Implementation of a multi-user chat interface based on Open WebUI and Ollama for local deployments.
- Remote access configuration using the host IP, reverse proxies such as Caddy, or Cloudflare tunnels.
- Hardware optimization for LLM inference using GPU acceleration on NVIDIA, AMD, and Apple Silicon.
- Extending capabilities through native RAG, custom Python functions, and the MCP protocol.
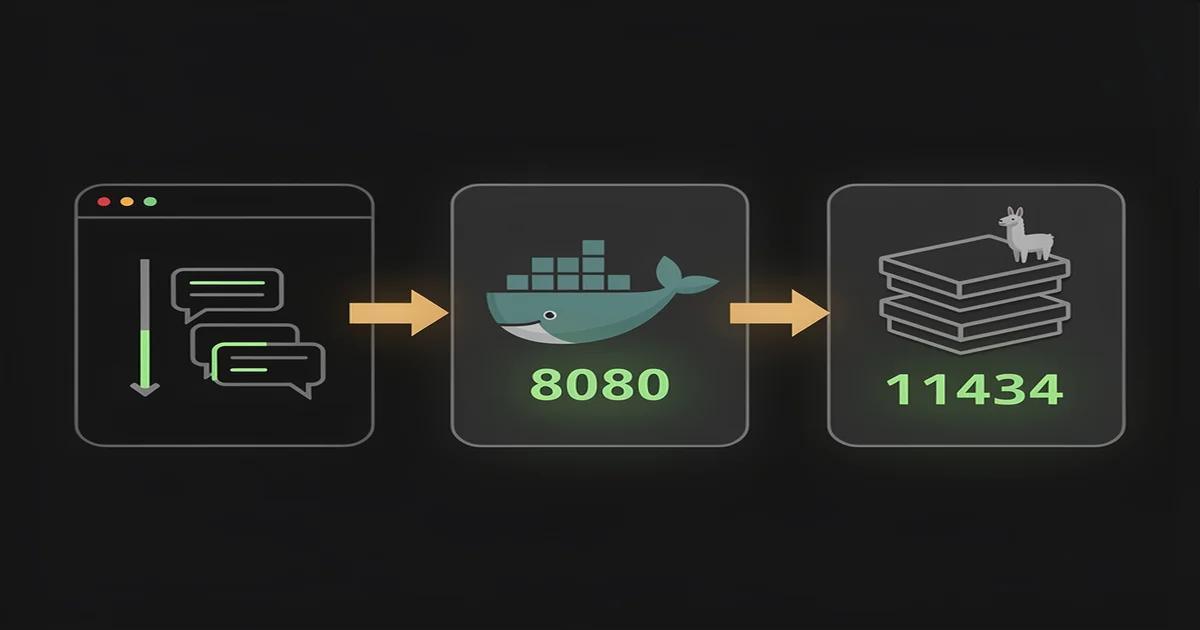
¿How do I share Open WebUI with other users on my local network? Imagine having the power of an advanced language model running in your own living room, without your data passing through the servers of any major tech company. Setting up a private AI environment is easier than ever thanks to the combination of Open WebUI and Ollamawhich together create an experience identical to that of ChatGPT but under your absolute control.
For many, the world of containers and hosting can seem a bit daunting at first, but once you understand that Docker is the engine It simplifies everything; things just flow naturally. Whether you want to use it on multiple computers at home or set up an assistant for your work team, the key is knowing how to expose the service so other devices can join in.
What exactly is this ecosystem?
To avoid confusion with the names, it's important to understand that we're talking about two different pieces that fit together perfectly. Ollama is the engineThe processor is responsible for downloading the models (such as Llama 3.2 or DeepSeek) and running them using your processor or graphics card. It's the technical layer that does the dirty work of processing the tokens.
On the other hand, Open WebUI is the visible faceIt's a polished, modern, multi-user web interface that connects to Ollama. Without it, you'd have to chat through a boring terminal; with it, you get chat history, document management, and a responsive design that works great even on mobile.
The great advantage of this combo is the total privacySince it doesn't rely on external API keys or token billing, you can experiment as much as you want without fear of exceeding your budget or someone reading your private prompts.
Quick installation and deployment with Docker
The quickest way to get it up and running is through Docker. If you already have Ollama installed on your system, you can launch Open WebUI with a command that maps the container's port 8080 to port 3000 on your machine. It's crucial to use the flag –add-host=host.docker.internal:host-gateway, especially on Linux, so that the container can communicate with the Ollama server running on the host.
For those looking for something more serious and professional, Docker Compose It's the winning option. It allows you to define both services in a single YAML file, managing shared networks and named volumes. This ensures that your conversations and settings survive even if you delete or update the container, preventing you from losing all the accumulated work.
If you work in business environments, there are Helm charts available for deployment in Kubernetesallowing for massive scalability and much more robust persistent storage management.
How to open access to other users on your network
This is where many get stuck. By default, if you enter localhost:3000Only you can see the website. For your partner, colleague, or another PC to access it, you must use the local IP address from your server (for example, http://192.168.1.15:3000If it doesn't load, it's most likely that the Windows or Ubuntu firewall is blocking the port.
If you want to take things to the next level and not depend on changing IPs, you can use a reverse proxy. Caddy is a gem Because of its simplicity; with a five-line file you can obtain an automatic SSL certificate and access it using a clean domain. If you don't have control over the DNS, the Cloudflare Tunnels They are a lifesaver, as they expose the web without needing to open ports on your router.
A vital security tip: never release this onto the open internet without protection. Although user registration is enabled by default, ideally you should disable the registration option in the administration panel once you have created the necessary accounts to prevent any unknown person from sneaking onto your server.
Accelerating performance with GPUs
There's nothing more frustrating than an AI that responds at a snail's pace. To avoid this, it's crucial that Ollama detects your GPUIf you have an NVIDIA card, you need the NVIDIA Container Toolkit for the engine to access the VRAM. For AMD, ROCm is used on Linux to achieve competitive performance.
For Mac users, there is one important detail: runs Ollama natively And not within Docker. This is because Docker on macOS doesn't allow direct access to the Metal GPU, and if you do, the model will run on the CPU, turning your powerful M2 or M3 chip into an outdated computer.
Depending on your hardware, the speed will vary. An Apple Silicon chip can reach... 50 tokens per second with smaller models like Llama 3.2, while denser models will require more RAM and patience, but will always be faster than any software emulation.
Powering AI with RAG, Functions, and MCP
Open WebUI is not just a chat window; it's an extensible platform. One of its best features is... native RAG (Augmented Generation by Retrieval). Basically, you can upload your own PDFs or Word documents, and the AI will use them as a knowledge base. By typing the # symbol in the chat, you can invoke a specific collection of documents for ultra-precise responses.
If you know a little Python, you can create Functions and PipelinesThe features allow you to add custom buttons to the interface or filter message content (for example, to delete sensitive emails before they reach the model). Pipelines, on the other hand, act as external routers that can connect your chat with other tools.
Furthermore, the arrival of Model Context Protocol (MCP) It allows your local AI to interact with external tools like Slack, GitHub, or your own local files in a standardized way, turning chat into a true productive agent.
Solving common problems
The most common error is that Open WebUI loads but the model list is empty. This happens because the container isn't reaching Ollama. The solution is usually to configure the variable. OLLAMA_BASE_URL correctly and ensure that Ollama is not linked only to 127.0.0.1, until 0.0.0.0 to accept external connections.
Regarding the RAG, if you notice that the citations are not accurate, try reduce fragment size (chunk size). If the chunks are too large, they can saturate the context window of small models, causing the AI to lose track of the original question.
To keep the system up to date, simply perform a docker pull from the most recent image and restart the container. Thanks to the persistent data volumesYou won't lose a single message or any of your custom settings during the update.
Having an AI server at home is an incredible experience that combines privacy, the ability to learn about infrastructure, and the versatility of open models. From basic installation with a Docker command to advanced configuration with proxies and RAG knowledge bases, Open WebUI positions itself as the ultimate tool for those who don't want to depend on the cloud and prefer to manage their own computing power on the local network.

Passionate about technology since he was little. I love being up to date in the sector and, above all, communicating it. That is why I have been dedicated to communication on technology and video game websites for many years. You can find me writing about Android, Windows, MacOS, iOS, Nintendo or any other related topic that comes to mind.